Running on multiple instances
Every instance of an application shares one database, and the instances share each consumer’s work. More instances give a partitioned consumer more throughput, and every consumer a standby to fail over to.
Distribution
A partitioned consumer, the default, has each of its partitions applied by one instance at a time, spread over the instances that run it. A single-owner consumer is applied by one instance at a time as a whole, one message at a time; the others stand by. See Distribution for the concept.
| Partitioned (default) | Single-owner | |
|---|---|---|
Throughput |
grows with the instances |
one instance’s |
Order |
within each partition |
across all partitions, in order per source |
After a crash |
the crashed instance’s partitions move, within |
the whole consumer moves, within |
| Projection | Route consumer | |
|---|---|---|
Default |
|
|
One consumer’s own |
|
|
Messages at once on an instance |
|
no setting |
In memory |
an |
— |
spring:
  ddd:
    cqrs:
      projections:
        ledger-totals:
          distribution: single-owner
    routing:
      consumers:
        audit:
          distribution: single-owner
A projection’s concurrency-limit only lowers what spring.ddd.messaging.consumer.executor allows an instance.
A limit of 1 applies a partitioned projection in position order on its instance.
A single-owner projection applies each source in position order across all its read models, so use it for a read model that needs one order.
Switching a consumer between partitioned and single-owner keeps its progress. During a rolling deploy that switches it, the single-owner side applies nothing until the other instances are gone. The projection lags, but the old and the new owner never apply a partition at the same time.
When an instance joins or leaves
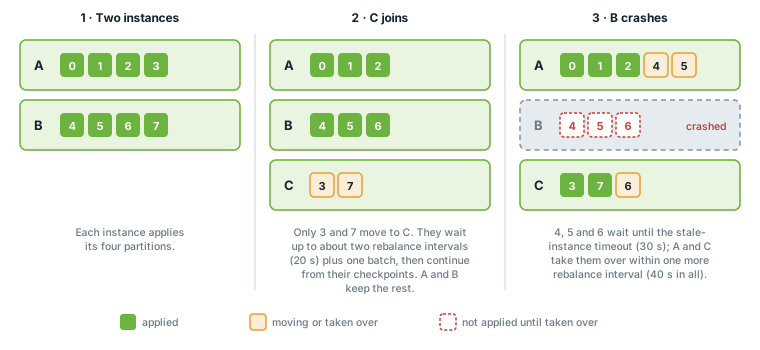
When an instance joins, only the partitions that move to it change owner; every other partition stays where it is. A moving partition is applied by no instance for up to about two rebalance intervals plus one batch, 20 seconds plus one batch by default, and then continues from its checkpoint on its new instance.
When an instance stops cleanly, it first finishes its work in flight, for up to graceful-shutdown-timeout, then releases its partitions, and the other instances take them over within one rebalance interval.
When an instance crashes, its partitions are not applied until stale-instance-timeout has passed; the other instances then take them over within one more rebalance interval: within 40 seconds of the crash by default.
A single-owner consumer’s standby takes over every partition within the same times.
No message is lost: the new owner continues from the checkpoint. A consumer whose writes commit with its checkpoints applies no message twice across a handover; any other consumer can apply again, after a crash, what it applied since its last saved checkpoint; see Delivery guarantees.
A consumer’s report shows each partition’s instance and whether it is OWNED, ORPHANED or UNCLAIMED; see the consumers endpoint.
The instances endpoint lists the running instances; see the instances endpoint.
Settings and handover times
spring:
  ddd:
    messaging:
      consumer:
        rebalance-interval: 10s
        stale-instance-timeout: 30s
        graceful-shutdown-timeout: 20s
heartbeat-interval: 5srebalance-interval, default10s-
How often an instance checks which partitions it should apply. It takes up new ones and gives up the ones that move away.
stale-instance-timeout, default30s-
How long an instance that stopped answering still counts as running. After a crash, its partitions wait this long. At least one second.
graceful-shutdown-timeout, default20s-
How long a stopping instance finishes its work in flight before it releases its partitions anyway. Keep it below
spring.lifecycle.timeout-per-shutdown-phase. heartbeat-interval, default5s-
How often an instance confirms that it is still running. Below half of
stale-instance-timeout.
rebalance-interval must be below stale-instance-timeout.
conflict-retry.max-delay must be below stale-instance-timeout.
conflict-retry.max-retries times max-delay must be below graceful-shutdown-timeout.
A startup with a setting outside these rules fails, naming it.
Handover times, with the defaults:
-
A clean stop: the stopping instance first finishes its work in flight, up to
graceful-shutdown-timeout; the other instances take its partitions within one rebalance interval of their release (10 s). -
A crash: within
stale-instance-timeoutplus one rebalance interval (40 s). -
A planned move, when an instance joins and takes partitions from the running ones: within two rebalance intervals plus one batch (20 s plus one batch).
Lowering the intervals shortens a handover at the cost of more queries against the database.
Caveats
-
A slow apply holds its partition’s handover, since the batch in flight finishes first. Bound what a listener calls: a transaction or query timeout on the apply, and timeouts on remote calls.
-
Every instance running a projection reads all of its topics, so the read load on the database grows with the number of instances.
-
A rolling deploy with a changed declaration has these effects:
-
An instance running another declaration stops applying the projection once it is rebuilt under a new one, and logs a warning, until restarted.
-
An instance started with the replaced declaration does not apply the projection, whatever its policy.
-
Only one declaration back is recognised.
-
A standby that took over later applies its own declaration, so finish a rolling deploy before relying on the rebuilt read models.
-
To roll back, deploy the earlier version and rebuild the projection through one of its instances.
-
-
An in-memory projection runs on every instance, with its own state and its own actions. Pausing, halting, resuming past a poison message and rebuilding reach the instance that answers only; see States.
Sagas
Each saga type is a consumer, partitioned by default, so the instances share its partitions as they share a projection’s; due deadlines are delivered by one instance at a time. A saga’s side effects are at-least-once: emit them as commands and make their handlers idempotent, since a retried apply sends its commands again. See Scaling on Event delivery.